DevOps Interview
1.Q. How are your day-to-day activities as a DevOps Engineer?
Monitoring infrastructure
Writing/maintaining IaC
Improving pipelines
Handling releases
Supporting dev teams
Troubleshooting incidents
On a typical day, I monitor production clusters, manage and improve our Jenkins pipelines, work on Terraform modules for resource provisioning, and collaborate with developers for application releases. I also handle incidents like pod failures or networking issues.”
2.What is a ConfigMap, and how is it different from a Secret?
ChatGPT said:
🔹 What is a ConfigMap in Kubernetes?
A ConfigMap is an object used to store non-sensitive configuration data in key-value pairs. It decouples configuration artifacts from container images so that your application can be more portable and environment-agnostic.
🔹 What is a Secret in Kubernetes?
A Secret is also a key-value store, but it is specifically designed to store sensitive data such as passwords, tokens, SSH keys, and certificates. Secrets are base64-encoded and can be mounted as files or exposed as environment variables.
🔸 Key Differences Between ConfigMap and Secret
| Feature | ConfigMap | Secret |
| Purpose | Store non-sensitive config data | Store sensitive data like credentials |
| Encoding | Plaintext | Base64-encoded (not encrypted by default) |
| Access Restrictions | Same as any resource | More restrictive access via RBAC |
| Default Storage | Stored in etcd as plain text | Stored in etcd but can be encrypted at rest |
| Use Cases | App settings, URLs, feature flags | Passwords, API keys, tokens |
🔸 Example: ConfigMap YAML
yamlCopyEditapiVersion: v1
kind: ConfigMap
metadata:
  name: my-config
data:
  APP_MODE: production
  LOG_LEVEL: debug
🔸 Example: Secret YAML
yamlCopyEditapiVersion: v1
kind: Secret
metadata:
  name: my-secret
type: Opaque
data:
  DB_PASSWORD: cGFzc3dvcmQ=     # "password" in base64
You can create a secret like this:
bashCopyEditkubectl create secret generic my-secret --from-literal=DB_PASSWORD=password
🔹 How They're Used in Pods
As environment variables:env: - name: APP_MODE valueFrom: configMapKeyRef: name: my-config key: APP_MODE
For secrets:
env:
- name: DB_PASSWORD
  valueFrom:
    secretKeyRef:
      name: my-secret
      key: DB_PASSWORD
🧠 TL;DR
| Use ConfigMap for: | Use Secret for: |
| App configs, flags | Passwords, tokens, keys |
| Log levels, URLs | SSH certs, DB credentials |
Let me know if you want a live example or need to mount these into a pod as volumes.
3.How do you check network connectivity between two servers?
ChatGPT said:
To check network connectivity between two servers, you can use a combination of basic and advanced tools depending on the depth of diagnostics you need.
🔹 1. Ping – Check basic network reachability
ping <destination-ip-or-hostname>
Example:
ping server2.example.com
✅ Verifies:
Network is reachable
ICMP is allowed (some firewalls block it)
🔹 2. Traceroute – Show network path and latency per hop
traceroute <destination>
Example:
traceroute server2.example.com
✅ Verifies:
Intermediate hops
Latency and where the path is breaking
📦 Install if missing:
tsudo apt install traceroute    # Debian/Ubuntu
sudo yum install traceroute    # RHEL/CentOS
🔹 3. Telnet / Netcat (nc) – Check if a port is open on a remote server
telnet <destination> <port>
Example:
telnet server2.example.com 22
Or use nc (netcat):
bashCopyEditnc -zv server2.example.com 22
✅ Verifies:
- TCP port connectivity (SSH, HTTP, DB ports, etc.)
🔹 4. SSH – Try to connect directly (if SSH is open)
ssh user@server2.example.com
✅ Verifies:
- Network + port 22 + authentication
🔹 5. curl / wget – Test web service or API endpoint
curl http://server2.example.com:8080
✅ Verifies:
HTTP connectivity
Service response (status codes, headers)
🔹 6. nmap – Scan ports on a remote server
nmap -p 1-65535 server2.example.com
✅ Verifies:
- Which ports are open/filtered/closed
📦 Install if needed:
sudo apt install nmap
🔹 7. ip/ifconfig + netstat/ss – Debug local networking issues
Check local interfaces:
ip a
Check listening ports:
ss -tuln
🧠 Pro Tip: Combine tools
If ping works but telnet/nc to port fails → likely a firewall or port blocking issue.
If telnet works but curl fails → likely a service issue on the remote server.
Let me know the OS type and specific use case (e.g., Kubernetes node check, internal servers, across VPN) and I can tailor the commands more precisely.
4.Q. What is a NAT Gateway?
Allows private subnets to access the internet Without exposing resources to incoming trac Managed by AWS ✅ Scenarios “We had EC2 instances in private subnets that needed to pull Docker images from public repos. We placed a NAT Gateway in a public subnet, routing private subnet trac through it so those instances could reach the internet safely.” “In my last project, the private subnets for EC2 instances needed to pull OS updates from the internet. I used a NAT gateway in the public subnet, routing trac through it, while blocking inbound access to those instances.” Diagram Internet-> IGW → NAT Gateway → Private Subnet EC2 Advanced Q&A Q: Can a NAT Gateway receive inbound trac? A: No — it only handles outbound requests from private subnets. Best practices Always place a NAT gateway in a public subnet Remember, private subnet routes point to the NAT
5.Frequently asked Kubernetes questions with practical 𝘀𝗰𝗲𝗻𝗮𝗿𝗶𝗼𝘀.. you must read once
🧠 𝟭. 𝗖𝗵𝗲𝗰𝗸 𝗡𝗼𝗱𝗲 𝗛𝗲𝗮𝗹𝘁𝗵
“𝘐𝘴 𝘵𝘩𝘦 𝘤𝘭𝘶𝘴𝘵𝘦𝘳 𝘩𝘦𝘢𝘭𝘵𝘩𝘺?”
kubectl get nodes
kubectl describe node <node-name>
📦 𝟮. 𝗗𝗲𝗯𝘂𝗴 𝗮 𝗖𝗿𝗮𝘀𝗵𝗶𝗻𝗴 𝗣𝗼𝗱
“𝘞𝘩𝘺 𝘪𝘴 𝘮𝘺 𝘱𝘰𝘥 𝘧𝘢𝘪𝘭𝘪𝘯𝘨?”
kubectl logs <pod-name>
kubectl logs <pod-name> --previous
🖥️ 𝟯. 𝗘𝘅𝗲𝗰 𝗶𝗻𝘁𝗼 𝗮 𝗣𝗼𝗱
“𝘕𝘦𝘦𝘥 𝘴𝘩𝘦𝘭𝘭 𝘢𝘤𝘤𝘦𝘴𝘴 𝘧𝘰𝘳 𝘥𝘦𝘣𝘶𝘨𝘨𝘪𝘯𝘨.”
kubectl exec -it <pod-name> -- /bin/bash
🌐 𝟰. 𝗘𝘅𝗽𝗼𝘀𝗲 𝗮 𝗗𝗲𝗽𝗹𝗼𝘆𝗺𝗲𝗻𝘁
“𝘌𝘹𝘱𝘰𝘴𝘦 𝘢𝘱𝘱 𝘷𝘪𝘢 𝘕𝘰𝘥𝘦𝘗𝘰𝘳𝘵.”
kubectl expose deployment <name> --port=80 --target-port=8080 --type=NodePort
📈 𝟱. 𝗦𝗰𝗮𝗹𝗲 𝗬𝗼𝘂𝗿 𝗔𝗽𝗽
“𝘐𝘯𝘤𝘳𝘦𝘢𝘴𝘦 𝘱𝘰𝘥 𝘤𝘰𝘶𝘯𝘵 𝘵𝘰 𝘩𝘢𝘯𝘥𝘭𝘦 𝘵𝘳𝘢𝘧𝘧𝘪𝘤.”
kubectl scale deployment <name> --replicas=5
🔄 𝟲. 𝗨𝗽𝗱𝗮𝘁𝗲 𝗗𝗲𝗽𝗹𝗼𝘆𝗺𝗲𝗻𝘁 𝗜𝗺𝗮𝗴𝗲
“𝘙𝘰𝘭𝘭 𝘰𝘶𝘵 𝘢 𝘯𝘦𝘸 𝘢𝘱𝘱 𝘷𝘦𝘳𝘴𝘪𝘰𝘯.”
kubectl set image deployment/<name> <container>=<image>:<tag>
📍 𝟳. 𝗣𝗼𝗱-𝘁𝗼-𝗡𝗼𝗱𝗲 𝗠𝗮𝗽𝗽𝗶𝗻𝗴
“𝘞𝘩𝘦𝘳𝘦 𝘪𝘴 𝘵𝘩𝘪𝘴 𝘱𝘰𝘥 𝘳𝘶𝘯𝘯𝘪𝘯𝘨?”
kubectl get pods -o wide
🔐 𝟴. 𝗨𝘀𝗲 𝗦𝗲𝗰𝗿𝗲𝘁𝘀 𝗦𝗲𝗰𝘂𝗿𝗲𝗹𝘆
“𝘐𝘯𝘫𝘦𝘤𝘵 𝘋𝘉 𝘤𝘳𝘦𝘥𝘦𝘯𝘵𝘪𝘢𝘭𝘴 𝘪𝘯𝘵𝘰 𝘱𝘰𝘥𝘴.”
kubectl create secret generic db-creds --from-literal=username=admin --from-literal=password=pass123
📜 𝟵. 𝗔𝗽𝗽𝗹𝘆 𝗬𝗔𝗠𝗟 𝗖𝗵𝗮𝗻𝗴𝗲𝘀
“𝘜𝘱𝘥𝘢𝘵𝘦 𝘤𝘰𝘯𝘧𝘪𝘨 𝘷𝘪𝘢 𝘧𝘪𝘭𝘦.”
kubectl apply -f deployment.yaml
↩️ 𝟭𝟬. 𝗥𝗼𝗹𝗹𝗯𝗮𝗰𝗸 𝗮 𝗕𝗮𝗱 𝗗𝗲𝗽𝗹𝗼𝘆𝗺𝗲𝗻𝘁
“𝘜𝘯𝘥𝘰 𝘢 𝘧𝘢𝘪𝘭𝘦𝘥 𝘳𝘰𝘭𝘭𝘰𝘶𝘵.”
kubectl rollout undo deployment/<name>
⚠️ 𝟭𝟭. 𝗗𝗿𝗮𝗶𝗻 𝗮 𝗡𝗼𝗱𝗲
“𝘗𝘳𝘦𝘱 𝘯𝘰𝘥𝘦 𝘧𝘰𝘳 𝘮𝘢𝘪𝘯𝘵𝘦𝘯𝘢𝘯𝘤𝘦.”
kubectl drain <node-name> --ignore-daemonsets --delete-emptydir-data
🛑 𝟭𝟮. 𝗧𝗮𝗶𝗻𝘁 𝗮 𝗡𝗼𝗱𝗲
“𝘙𝘦𝘴𝘦𝘳𝘷𝘦 𝘢 𝘯𝘰𝘥𝘦 𝘧𝘰𝘳 𝘴𝘱𝘦𝘤𝘪𝘢𝘭 𝘸𝘰𝘳𝘬𝘭𝘰𝘢𝘥𝘴.”
kubectl taint nodes <name> key=value:NoSchedule
📂 𝟭𝟯. 𝗪𝗼𝗿𝗸 𝘄𝗶𝘁𝗵 𝗡𝗮𝗺𝗲𝘀𝗽𝗮𝗰𝗲𝘀
“𝘚𝘦𝘱𝘢𝘳𝘢𝘵𝘦 𝘦𝘯𝘷𝘪𝘳𝘰𝘯𝘮𝘦𝘯𝘵𝘴.”
kubectl create namespace dev kubectl config set-context --current --namespace=dev
🔍 𝟭𝟰. 𝗖𝗿𝗮𝘀𝗵𝗟𝗼𝗼𝗽𝗕𝗮𝗰𝗸𝗢𝗳𝗳 𝗗𝗲𝗯𝘂𝗴
“𝘗𝘰𝘥 𝘬𝘦𝘦𝘱𝘴 𝘳𝘦𝘴𝘵𝘢𝘳𝘵𝘪𝘯𝘨 — 𝘸𝘩𝘺?”
kubectl describe pod <name>
kubectl logs <name> --previous
𝗤. When auto-scaling instances, how do you manage the backend RDS database?
𝗔. To manage the backend RDS database during auto-scaling:
○ Enable Multi-AZ for high availability and automatic failover.
○ Use RDS Read Replicas to handle read-heavy traffic, reducing the load on the primary database.
○ Scale RDS vertically (instance size) or horizontally (read replicas) based on the database workload.
○ Monitor performance using Amazon CloudWatch and adjust as necessary.𝗤. Have you ever set up cross-account access for S3? For example, if the QA team needs access
to the production database.
-> Yes, I've set up cross-account access by:
○ Creating an IAM role in the production account with the necessary S3 permissions.
○ Establishing a trust relationship to allow the QA account to assume that role.
○ Using S3 bucket policies to grant access from the QA account.
○ QA team members can then assume the role using AWS STS (Security Token Service) to access the production S3 bucket.𝗤. How can an S3 account in Account A access an S3 account in Account B?
𝗔. Account A can access Account B’s S3 bucket by:
○ Setting up a bucket policy in Account B that grants Account A the necessary permissions.
○ Creating an IAM role in Account B with permissions for S3 and allowing Account A to assume that role via a trust policy.
○ Using AWS STS to assume the role from Account A and access the S3 bucket in Account B.𝗤. Are you familiar with lifecycle management in S3 buckets? How do you set up lifecycle policies?
𝗔. Yes, lifecycle management in S3 allows you to define rules to transition objects between different storage classes or delete them after a certain period. Lifecycle policies can be set up using the S3 Management Console, AWS CLI, or Terraform by specifying the transitions and expiration actions in a JSON configuration file.𝗤. Can you explain the STS assume role policy?
𝗔. The STS (Security Token Service) AssumeRole policy allows a user or service to assume a
role in a different account or within the same account. This provides temporary security credentials with the permissions associated with the assumed role, enabling cross-account access or delegation of permissions.𝗤. What are the types of storage accounts in AWS S3?
𝗔. In AWS S3, the different storage classes include:
○ S3 Standard
○ S3 Intelligent-Tiering
○ S3 Standard-IA (Infrequent Access)
○ S3 One Zone-IA
○ S3 Glacier
○ S3 Glacier Deep Archive𝗤. What is the maximum number of S3 buckets you can
create?
Ans. 100𝗤. How many total VPCs per account/region and subnets per
VPC can you have?
Ans. 5, 200𝗤. 𝗖𝗮𝗻 𝘆𝗼𝘂 𝘀𝗵𝗮𝗿𝗲 𝗮𝗻 𝗶𝗻𝘀𝘁𝗮𝗻𝗰𝗲 𝘄𝗵𝗲𝗿𝗲 𝘆𝗼𝘂 𝗽𝗿𝗼𝘃𝗶𝗱𝗲𝗱 𝗮 𝘀𝗼𝗹𝘂𝘁𝗶𝗼𝗻 𝗳𝗼𝗿 𝗰𝗼𝘀𝘁 𝗼𝗽𝘁𝗶𝗺𝗶𝘇𝗮𝘁𝗶𝗼𝗻 𝘄𝗵𝗶𝗹𝗲 𝗺𝗮𝗻𝗮𝗴𝗶𝗻𝗴 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲 𝗮𝗹𝗹𝗼𝗰𝗮𝘁𝗶𝗼𝗻?
Our cloud infrastructure was over-provisioned, leading to unnecessary costs.
I implemented auto-scaling based on actual usage metrics and utilized spot instances for non-critical workloads.
Additionally, I restructured the storage solution by moving infrequently accessed data to lower-cost storage classes. These changes resulted in a significant reduction in our monthly cloud expenses without compromising performance.𝗤. 𝗖𝗮𝗻𝗮𝗿𝘆 𝗗𝗲𝗽𝗹𝗼𝘆𝗺𝗲𝗻𝘁: Gradually rolling out the new version to a small subset of users before a full deployment.
𝗤. 𝗥𝗼𝗹𝗹𝗶𝗻𝗴 𝗗𝗲𝗽𝗹𝗼𝘆𝗺𝗲𝗻𝘁: Incrementally updating instances or servers with the new version, ensuring at least some instances are always running the old version.
𝗤. 𝗗𝗲𝘀𝗰𝗿𝗶𝗯𝗲 𝗮 𝘀𝗶𝘁𝘂𝗮𝘁𝗶𝗼𝗻 𝘄𝗵𝗲𝗿𝗲 𝘁𝗵𝗲 𝗲𝗻𝘁𝗶𝗿𝗲 𝗽𝗿𝗼𝗱𝘂𝗰𝘁𝗶𝗼𝗻 𝗶𝗻𝘀𝘁𝗮𝗻𝗰𝗲 𝗰𝗿𝗮𝘀𝗵𝗲𝗱, 𝗮𝗻𝗱 𝘆𝗼𝘂 𝗵𝗮𝗱 𝘁𝗼 𝗳𝗶𝘅 𝗶𝘁 𝗾𝘂𝗶𝗰𝗸𝗹𝘆.
In one instance, our production server crashed due to a
memory leak in the application. I quickly identified the issue using monitoring tools like Prometheus and logs from ELK Stack.
To resolve it, I restarted the affected services and temporarily scaled up the infrastructure to handle the load. I then worked with the development team to identify and fix the memory leak, ensuring it didn’t happen again.𝗤.𝗖𝗹𝗼𝘂𝗱 𝗡𝗔𝗧 𝗚𝗮𝘁𝗲𝘄𝗮𝘆:
Provides outbound internet access for instances in a private network without exposing them to inbound traffic.
Used for secure, private instances that need internet access without being directly accessible from the internet.𝗤. 𝗩𝗣𝗖 𝗣𝗲𝗲𝗿𝗶𝗻𝗴: A network connection between two VPCs that allows traffic to be routed between them using private IP addresses. This is useful for connecting resources across different VPCs without going over the public internet.
𝗤. 𝗛𝗮𝗻𝗱𝗹𝗶𝗻𝗴 𝗠𝘂𝗹𝘁𝗶𝗽𝗹𝗲 𝗠𝗶𝗰𝗿𝗼𝘀𝗲𝗿𝘃𝗶𝗰𝗲𝘀: Use Kubernetes namespaces to isolate microservices, and manage their deployment using Helm charts or a CI/CD tool like Jenkins, ArgoCD, or GitLab CI/CD. Implement service discovery, networking, and security policies to ensure seamless communication between microservices.
𝗤. 𝗛𝗮𝘃𝗲 𝘆𝗼𝘂 𝘄𝗼𝗿𝗸𝗲𝗱 𝘄𝗶𝘁𝗵 𝗔𝘂𝘁𝗼 𝗦𝗰𝗮𝗹𝗶𝗻𝗴 𝗚𝗿𝗼𝘂𝗽𝘀 (𝗔𝗦𝗚)?
Yes, I have worked with ASGs to automatically scale the number of instances in response to demand. ASGs are configured with policies that adjust the desired capacity based on metrics such as CPU utilization, helping to maintain application performance and optimize costs.Member-only story
Kubernetes Troubleshooting —Understanding ImagePullBackOff (The Right Way!)
One of the first errors most beginners encounter (and even experienced engineers sometimes dread) in Kubernetes Cluster is:
🚨
ImagePullBackOffSounds scary? It’s actually not — once you understand what’s going on.
In this post, I’ll walk you through what this error means, how to reproduce it on your local cluster, and most importantly, how to fix it — whether it’s caused by a bad image name, a private registry, or a simple copy-paste mistake.
What Is ImagePullBackOff in Kubernetes?
The name says it all — this error is related to pulling a container image in your Kubernetes cluster. When you deploy a pod (whether through a
Pod,Deployment,StatefulSet, etc.), Kubernetes needs to pull the container image from a registry like Docker Hub, ECR, or ACR.When that fails for any reason, Kubernetes throws this error.
That’s where the name comes from:
ImagePull: Kubernetes is trying to download the image.BackOff: It's backing off between retries.
Put them together: ImagePullBackOff.
Two Common Scenarios That Cause ImagePullBackOff
Scenario 1: Invalid or Non-Existent Image Name
Let’s say you meant to use the image nginx:1.14.2, but you accidentally typed:
image: ngiNY:1.14.2 # typo!
That image doesn’t exist on Docker Hub (or anywhere). Kubernetes will try to pull it, fail, and eventually hit ImagePullBackOff.
The same goes for specifying the wrong tag. If foolapp:1.1.1 was deleted from your registry, referencing it will cause the same error.
Scenario 2: Private Images Without Access
Let’s say you’re trying to pull an image from your private Docker Hub repo or ECR.
Unless Kubernetes has the right credentials, it won’t be able to access that image. That leads to — you guessed it — ImagePullBackOff.
Let’s Solve ImagePullBackOff (The Fun Part)
If you want to play around with this error and troubleshoot it yourself:
Start a local cluster with Minikube or at KillerCoda.
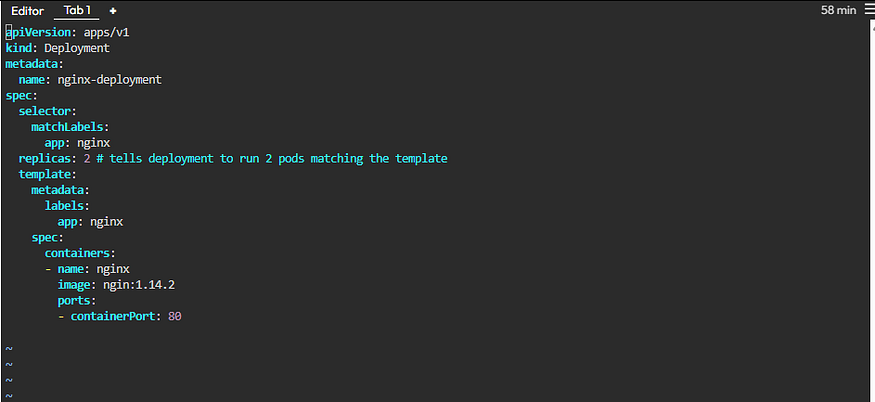
Create a deployment with a non-existent image:
    apiVersion: apps/v1
    kind: Deployment
    metadata:
      name: nginx-deployment
    spec:
      replicas: 1
      selector:
        matchLabels:
          app: nginx
      template:
        metadata:
          labels:
            app: nginx
        spec:
          containers:
          - name: nginx
            image: ngiNY:1.14.2  # <-- typo on purpose
    kubectl apply -f nginx-deploy.yaml
    kubectl get pods -w
You’ll first see ErrImagePull, and after a few retries, Kubernetes will enter ImagePullBackOff.
What Does “BackOff” Mean in Kubernetes?
Kubernetes doesn’t give up easily.
When an image pull fails, it waits a bit and retries. If it fails again, it waits a little longer, and so on.
That increasing delay between retries is called backoff — hence the term ImagePullBackOff.
It’s a retry loop, where the interval increases exponentially to avoid hammering the registry unnecessarily.
How to Troubleshoot
Here are a few simple but powerful commands to troubleshoot image pull errors:
Check Events of Pods in detail in Kubernetes Cluster
kubectl describe pod <pod-name>
This gives you the exact reason why the image couldn’t be pulled — wrong name, unauthorized access, etc.
Watch Status of Pods
kubectl get pods -w
This keeps you updated on the status of the pod in real time.
Fixing Private Image Pull Issues (The Right Way)
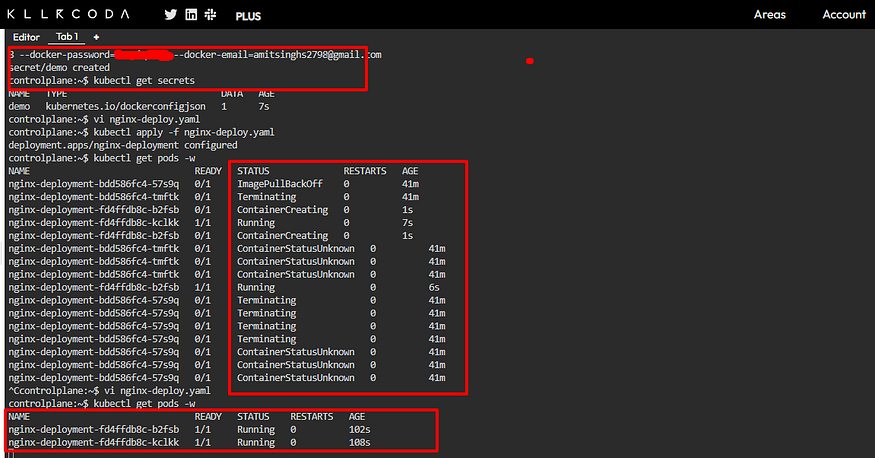
If your image is in a private repo, Kubernetes needs a secret to access it.
Step 1: Create a Docker Registry Secret
    kubectl create secret docker-registry demo-secret \
      --docker-username=<your-username> \
      --docker-password=<your-password> \
      --docker-email=<your-email> \
      --docker-server=https://index.docker.io/v1/
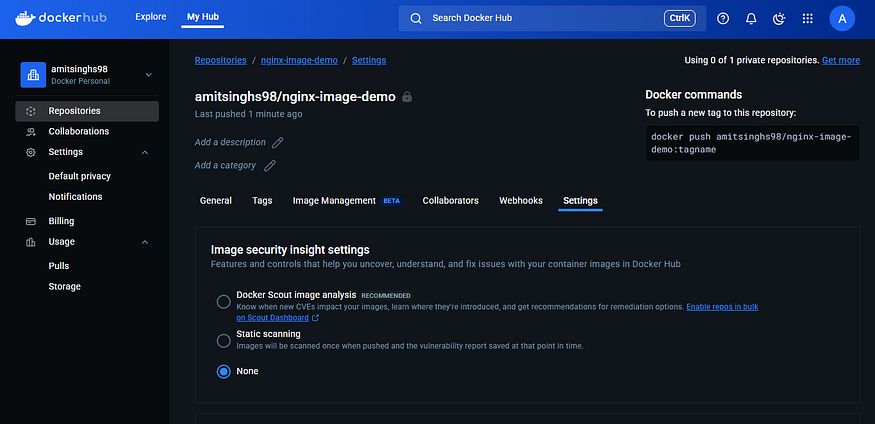
For AWS ECR or Azure, change the docker-server accordingly.
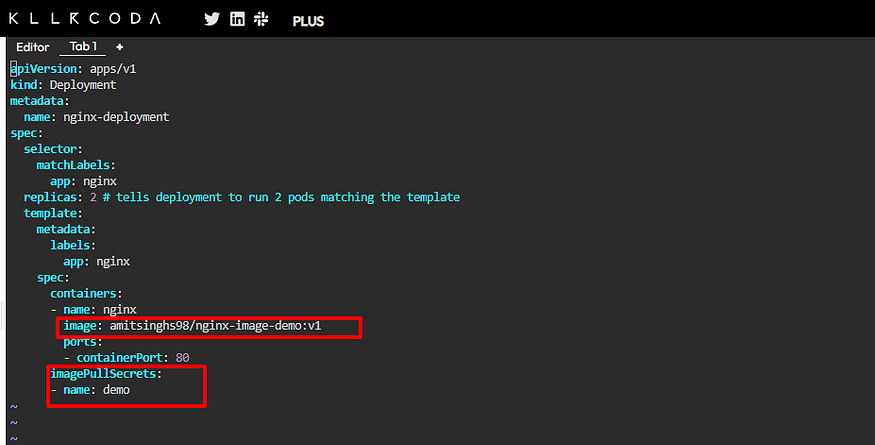
Step 2: Reference the Secret in Your YAML
    spec:
      imagePullSecrets:
        - name: demo-secret
Kubernetes now knows how to authenticate and pull your private image.
Recap: When You See ImagePullBackOff…
Check your image name — typos and wrong tags are super common.
Is the image private? — use
imagePullSecretsto fix auth issues.Use
kubectl describe podto get the real reason.BackOff means retry loop — Kubernetes is trying its best for you
Your Kubernetes Troubleshooting Toolkit
Here are some go-to commands always useful for me:
    kubectl get pods -w         # live watch
    kubectl describe pod <pod>  # detailed debug info
    kubectl get events          # useful for checking what Kubernetes is doing
And if you’re ever stuck, this kubectl cheat sheet is your best friend.
Bonus: Pulling from AWS ECR
Pulling from AWS ECR if working with AWS Cloud? It’s the same concept — just with a different --docker-server and a special command to get your token:
    aws ecr get-login-password | kubectl create secret docker-registry ecr-secret \
      --docker-server=<your-registry-url> \
      --docker-username=AWS \
      --docker-password-stdi
Update your deployment just like before to reference ecr-secret.
Pro Tips: Remember for ImagePullBackOff
Always double-check your image name and tag before deploying.
Use
kubectl describeto get clear info on what went wrong.Remember,
ImagePullBackOffusually starts asErrImagePull— it just means Kubernetes is retrying.
Wrapping Up
ImagePullBackOff = Either your image doesn’t exist, or you don’t have access to it.
Fixing it is usually a matter of checking names, tags, or credentials. Simple — once you know what to look for.
𝗜𝗻𝘁𝗲𝗿𝘃𝗶𝗲𝘄 𝗤𝘂𝗲𝘀𝘁𝗶𝗼𝗻𝘀 𝗳𝗼𝗿 𝗟𝗶𝗻𝘂𝘅 / 𝗗𝗲𝘃𝗢𝗽𝘀 𝗜𝗻𝘁𝗲𝗿𝘃𝗶𝗲𝘄 hashtag#MustCheck
𝟭. 𝗨𝘀𝗲𝗿 𝗿��𝗽𝗼𝗿𝘁𝘀 𝗵𝗶𝗴𝗵 𝗖𝗣𝗨 𝘂𝘀𝗮𝗴𝗲. 𝗪𝗵𝗮𝘁 𝗱𝗼 𝘆𝗼𝘂 𝗱𝗼?
𝗦𝘁𝗲𝗽𝘀:
• Run top or htop to see real-time CPU usage.
• Use ps aux --sort=-%cpu | head to find the top processes.
• Investigate the PID using strace -p <pid> or lsof -p <pid>.Check if it’s a normal load (e.g., backup, cron job) or a runaway process.
𝟮. 𝗗𝗶𝘀𝗸 𝘀𝗽𝗮𝗰𝗲 𝗶𝘀 𝗳𝘂𝗹𝗹. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝘁𝗿𝗼𝘂𝗯𝗹𝗲𝘀𝗵𝗼𝗼𝘁 𝗮𝗻𝗱 𝗳𝗶𝘅 𝗶𝘁?𝗦𝘁𝗲𝗽𝘀:
• Run df -h to find which partition is full.
• Use du -sh /* and then du -sh /var/* etc. to drill down.
• Check /var/log/, /tmp, large files with find / -size +500M.Clean up logs, old files, or move/archive if needed.
𝟯. 𝗬𝗼𝘂 𝗰𝗮𝗻'𝘁 𝗦𝗦𝗛 𝗶𝗻𝘁𝗼 𝗮 𝘀𝗲𝗿𝘃𝗲𝗿. 𝗪𝗵𝗮𝘁 𝗰𝗼𝘂𝗹𝗱 𝗯𝗲 𝘁𝗵𝗲 𝗶𝘀𝘀𝘂𝗲?𝗖𝗵𝗲𝗰𝗸𝘀:
• Network: ping server_ip, traceroute.
• Port: nc -zv server_ip 22 or telnet server_ip 22.
• Firewall: Check iptables, firewalld, security groups (cloud).
• Service: Is sshd running? systemctl status sshdAuth: Are permissions on ~/.ssh/authorized_keys correct?
𝟰. 𝗔 𝘂𝘀𝗲𝗿 𝗰𝗮𝗻’𝘁 𝗿𝘂𝗻 𝘀𝘂𝗱𝗼. 𝗪𝗵𝗮𝘁 𝗱𝗼 𝘆𝗼𝘂 𝗰𝗵𝗲𝗰𝗸?𝗦𝘁𝗲𝗽𝘀:
• Check with groups username — is the user in sudo group?
• Check /etc/sudoers and /etc/sudoers.d/.
• Use sudo -l -U username to list allowed sudo commands.Check /etc/passwd and /etc/shadow for account issues.
𝟱. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗴𝗶𝘃𝗲 𝗮 𝘂𝘀𝗲𝗿 𝗽𝗲𝗿𝗺𝗶𝘀𝘀𝗶𝗼𝗻 𝘁𝗼 𝗿𝘂𝗻 𝗼𝗻𝗹𝘆 𝗼𝗻𝗲 𝗰𝗼𝗺𝗺𝗮𝗻𝗱 𝘄𝗶𝘁𝗵 𝘀𝘂𝗱𝗼?
𝗔𝗻𝘀𝘄𝗲𝗿:
Edit sudoers with visudo:
username ALL=(ALL) NOPASSWD: /usr/bin/systemctl restart apache2This allows only restarting Apache with sudo.
𝟲. 𝗧𝗵𝗲 𝘄𝗲𝗯𝘀𝗶𝘁𝗲 𝗵𝗼𝘀𝘁𝗲𝗱 𝗼𝗻 𝘆𝗼𝘂𝗿 𝗟𝗶𝗻𝘂𝘅 𝘀𝗲𝗿𝘃𝗲𝗿 𝗶𝘀 𝗱𝗼𝘄𝗻. 𝗪𝗵𝗮𝘁 𝗱𝗼 𝘆𝗼𝘂 𝗰𝗵𝗲𝗰𝗸?𝗖𝗵𝗲𝗰𝗸𝗹𝗶𝘀𝘁:
• Ping the server.
• Check systemctl status apache2 or nginx.
• Confirm the port is open: netstat -tuln | grep 80
• Check firewall: ufw status, iptables -L.Check logs: /var/log/nginx/error.log or /var/log/apache2/error.log
𝟳. 𝗡𝗲𝘁𝘄𝗼𝗿𝗸 𝗶𝘀 𝘀𝗹𝗼𝘄. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗱𝗶𝗮𝗴𝗻𝗼𝘀𝗲 𝗶𝘁?𝗧𝗼𝗼𝗹𝘀:
• ping, traceroute, mtr — path and packet loss.
• iftop, nload — bandwidth usage.
• ss -tuln — open ports and connections.
• Look for high RX/TX errors: ifconfig or ip -s link.• 𝟴. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗳𝗶𝗻𝗱 𝗼𝘂𝘁 𝘄𝗵𝗶𝗰𝗵 𝗽𝗿𝗼𝗰𝗲𝘀𝘀 𝗶𝘀 𝘂𝘀𝗶𝗻𝗴 𝗮 𝘀𝗽𝗲𝗰𝗶𝗳𝗶𝗰 𝗽𝗼𝗿𝘁?
sudo lsof -i :<port>sudo netstat -tulnp | grep <port>𝟵. 𝗔 𝘀𝗲𝗿𝘃𝗶𝗰𝗲 𝗳𝗮𝗶𝗹𝘀 𝘁𝗼 𝘀𝘁𝗮𝗿𝘁. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗱𝗲𝗯𝘂𝗴 𝗶𝘁?
• systemctl status servicename
• journalctl -xe for system logs
• Check config syntax: nginx -t, named-checkconf, etc.
Check port conflicts: netstat -tuln𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗳𝗼𝗿𝗺𝗮𝘁 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗰𝗼𝗻𝗳𝗶𝗴𝘂𝗿𝗮𝘁𝗶𝗼𝗻 𝗳𝗶𝗹𝗲𝘀?
𝘵𝘦𝘳𝘳𝘢𝘧𝘰𝘳𝘮 𝘧𝘮𝘵𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝘂𝘀𝗲 𝘀𝗲𝗻𝘀𝗶𝘁𝗶𝘃𝗲 𝗱𝗮𝘁𝗮 𝗹𝗶𝗸𝗲 𝗰𝗿𝗲𝗱𝗲𝗻𝘁𝗶𝗮𝗹𝘀 𝗶𝗻 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺?
Sensitive data can be managed securely in Terraform using environment variables, secret management tools, or Terraform variables with the sensitive attribute. Avoid hardcoding sensitive values in .tf files. Tools like HashiCorp Vault or AWS Secrets Manager can store and retrieve credentials. Secure your state file as it may contain sensitive outputs. Use .gitignore to exclude sensitive files from version control.
𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝘃𝗮𝗹𝗶𝗱𝗮𝘁𝗲 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗰𝗼𝗻𝗳𝗶𝗴𝘂𝗿𝗮𝘁𝗶𝗼𝗻 𝗳𝗶𝗹𝗲𝘀?
𝘵𝘦𝘳𝘳𝘢𝘧𝘰𝘳𝘮 𝘷𝘢𝘭𝘪𝘥𝘢𝘵𝘦𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗹𝗶𝘀𝘁 𝗮𝗹𝗹 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝘄𝗼𝗿𝗸𝘀𝗽𝗮𝗰𝗲𝘀?
𝘵𝘦𝘳𝘳𝘢𝘧𝘰𝘳𝘮 𝘸𝘰𝘳𝘬𝘴𝘱𝘢𝘤𝘦 𝘭𝘪𝘴𝘵𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗿𝗲𝗺𝗼𝘃𝗲 𝗮 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲 𝘄𝗶𝘁𝗵𝗼𝘂𝘁 𝗱𝗲𝗹𝗲𝘁𝗶𝗻𝗴 𝗶𝘁 𝗳𝗿𝗼𝗺 𝘁𝗵𝗲 𝗶𝗻𝗳𝗿𝗮𝘀𝘁𝗿𝘂𝗰𝘁𝘂𝗿𝗲?
𝘵𝘦𝘳𝘳𝘢𝘧𝘰𝘳𝘮 𝘴𝘵𝘢𝘵𝘦 𝘳𝘮 <𝘳𝘦𝘴𝘰𝘶𝘳𝘤𝘦_𝘯𝘢𝘮𝘦>𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗰𝗿𝗲𝗮𝘁𝗲 𝗮 𝗻𝗲𝘄 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝘄𝗼𝗿𝗸𝘀𝗽𝗮𝗰𝗲?
𝘵𝘦𝘳𝘳𝘢𝘧𝘰𝘳𝘮 𝘸𝘰𝘳𝘬𝘴𝘱𝘢𝘤𝘦 𝘯𝘦𝘸 <𝘸𝘰𝘳𝘬𝘴𝘱𝘢𝘤𝘦_𝘯𝘢𝘮𝘦>𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗿𝗲𝗳𝗿𝗲𝘀𝗵 𝘁𝗵𝗲 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝘀𝘁𝗮𝘁𝗲 𝗳𝗶𝗹𝗲 𝘄𝗶𝘁𝗵 𝘁𝗵𝗲 𝗰𝘂𝗿𝗿𝗲𝗻𝘁 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲 𝘀𝘁𝗮𝘁𝗲𝘀?
𝘵𝘦𝘳𝘳𝘢𝘧𝘰𝘳𝘮 𝘳𝘦𝘧𝘳𝘦𝘴𝘩𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗹𝗼𝗰𝗸 𝘁𝗵𝗲 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝘀𝘁𝗮𝘁𝗲 𝗳𝗶𝗹𝗲?
State locking is enabled by default in remote backends like S3 with DynamoDB. Ensure your backend configuration supports locking. But now you can do state locking with just S3 and dynamoDB is not required.𝗤. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝘀𝘄𝗶𝘁𝗰𝗵 𝗯𝗲𝘁𝘄𝗲𝗲𝗻 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝘄𝗼𝗿𝗸𝘀𝗽𝗮𝗰𝗲𝘀?
𝘵𝘦𝘳𝘳𝘢𝘧𝘰𝘳𝘮 𝘸𝘰𝘳𝘬𝘴𝘱𝘢𝘤𝘦 𝘴𝘦𝘭𝘦𝘤𝘵 <𝘸𝘰𝘳𝘬𝘴𝘱𝘢𝘤𝘦_𝘯𝘢𝘮𝘦>𝗤1. 𝗛𝗼𝘄 𝗵𝗮𝘃𝗲 𝘆𝗼𝘂 𝗶𝗻𝗷𝗲𝗰𝘁𝗲𝗱 𝘁𝗵𝗲 𝘀𝗲𝗰𝗿𝗲𝘁𝘀 𝗶𝗻 𝗖𝗼𝗻𝗳𝗶𝗴𝗠𝗮𝗽𝘀?
𝗔𝗻𝘀𝘄𝗲𝗿: Secrets should not be injected in ConfigMaps as ConfigMaps are not designed for sensitive data. Instead, Kubernetes Secrets should be used. Secrets can be injected into pods via environment variables or mounted as files.𝗤2. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗳𝗶𝗻𝗱 𝘄𝗵𝗶𝗰𝗵 𝗽𝗼𝗱 𝗶𝘀 𝘁𝗮𝗸𝗶𝗻𝗴 𝗺𝗼𝗿𝗲 𝘀𝘆𝘀𝘁𝗲𝗺 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲𝘀 𝗮𝗰𝗿𝗼𝘀𝘀 𝗻𝗼𝗱𝗲𝘀 𝘂𝘀𝗶𝗻𝗴 𝗸𝘂𝗯𝗲𝗰𝘁𝗹?
𝗔𝗻𝘀𝘄𝗲𝗿: Use 𝘬𝘶𝘣𝘦𝘤𝘵𝘭 𝘵𝘰𝘱 𝘱𝘰𝘥 --𝘢𝘭𝘭-𝘯𝘢𝘮𝘦𝘴𝘱𝘢𝘤𝘦𝘴 to list resource usage by pods.
Combine it with 𝘬𝘶𝘣𝘦𝘤𝘵𝘭 𝘥𝘦𝘴𝘤𝘳𝘪𝘣𝘦 𝘱𝘰𝘥 <𝘱𝘰𝘥-𝘯𝘢𝘮𝘦> to get detailed resource usage.𝗤3. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗸𝗻𝗼𝘄 𝘄𝗵𝗶𝗰𝗵 𝘄𝗼𝗿𝗸𝗲𝗿 𝗻𝗼𝗱𝗲 𝗶𝘀 𝗰𝗼𝗻𝘀𝘂𝗺𝗶𝗻𝗴 𝗺𝗼𝗿𝗲 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲𝘀 𝗮𝗰𝗿𝗼𝘀𝘀 𝘁𝗵𝗲 𝗰𝗹𝘂𝘀𝘁𝗲𝗿𝘀 𝘂𝘀𝗶𝗻𝗴 𝗸𝘂𝗯𝗲𝗰𝘁𝗹?
𝗔𝗻𝘀𝘄𝗲𝗿: Use kubectl top nodes to see resource consumption across nodes. This will show CPU and memory usage on each node.𝗤4. 𝗪𝗵𝗮𝘁 𝗮𝗿𝗲 𝘁𝗵𝗲 𝘀𝘁𝗲𝗽𝘀 𝗳𝗼𝗿 𝗰𝗼𝗻𝗳𝗶𝗴𝘂𝗿𝗶𝗻𝗴 𝗣𝗿𝗼𝗺𝗲𝘁𝗵𝗲𝘂𝘀 𝗮𝗻𝗱 𝗚𝗿𝗮𝗳𝗮𝗻𝗮 𝗳𝗼𝗿 𝗺𝗼𝗻𝗶𝘁𝗼𝗿𝗶𝗻𝗴 𝗞𝘂𝗯𝗲𝗿𝗻𝗲𝘁𝗲𝘀 𝗰𝗹𝘂𝘀𝘁𝗲𝗿𝘀?
𝗔𝗻𝘀𝘄𝗲𝗿:
1. Deploy Prometheus using Helm or a custom YAML configuration.
2. Set up Kubernetes service discovery for Prometheus.
3. Deploy Grafana and configure it to use Prometheus as a data source.
4. Import Kubernetes monitoring dashboards in Grafana.
5. Set up alerting rules in Prometheus as needed.𝗤5. 𝗪𝗵𝗮𝘁 𝗶𝘀 𝘀𝗲𝘀𝘀𝗶𝗼𝗻 𝗮𝗳𝗳𝗶𝗻𝗶𝘁𝘆?
𝗔𝗻𝘀𝘄𝗲𝗿: Session affinity, also known as sticky sessions, is a concept in load balancing where requests from a particular user are consistently directed to the same server (or pod) in a multi-server environment.
This ensures that the user's session data, which might be stored locally on the server, remains accessible throughout the session.𝗤6. 𝗪𝗵𝗮𝘁 𝗶𝘀 𝗽𝗼𝗱 𝗮𝗳𝗳𝗶𝗻𝗶𝘁𝘆 𝗮𝗻𝗱 𝗶𝘁𝘀 𝘂𝘀𝗲 𝗰𝗮𝘀𝗲?
𝗔𝗻𝘀𝘄𝗲𝗿: Pod affinity is a feature in Kubernetes that allows you to specify rules for scheduling pods to run on
nodes that have other specified pods running on them. This can be useful when you want certain
pods to be located together due to factors like data locality, network latency, or shared resources.
𝗨𝘀𝗲 𝗖𝗮𝘀𝗲: An application where the frontend and backend services communicate frequently might
use pod affinity to ensure that both are scheduled on the same node to reduce network latency.1. 𝗪𝗵𝗮𝘁 𝗶𝘀 𝗿𝗲𝗺𝗼𝘁𝗲 𝘀𝘁𝗮𝘁𝗲 𝗶𝗻 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺?
Remote state in Terraform refers to storing the state file on a remote backend, such as Amazon S3, instead of locally. This facilitates collaboration and enables locking.2. 𝗛𝗼𝘄 𝗰𝗮𝗻 𝘆𝗼𝘂 𝗺𝗮𝗻𝗮𝗴𝗲 𝗺𝘂𝗹𝘁𝗶𝗽𝗹𝗲 𝗲𝗻𝘃𝗶𝗿𝗼𝗻𝗺𝗲𝗻𝘁𝘀 (𝗱𝗲𝘃, 𝗽𝗿𝗼𝗱) 𝘄𝗶𝘁𝗵 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺?
You can use Terraform workspaces or create separate directories for each environment, each with its own state file and variables.3. 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗵𝗮𝗻𝗱𝗹𝗲 𝗱𝗲𝗽𝗲𝗻𝗱𝗲𝗻𝗰𝗶𝗲𝘀 𝗯𝗲𝘁𝘄𝗲𝗲𝗻 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲𝘀 𝗶𝗻 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺?
Terraform automatically handles dependencies based on the resource definitions in your configuration. It will create resources in the correct order.
4. 𝗪𝗵𝗮𝘁 𝗶𝘀 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺'𝘀 "𝗮𝗽𝗽𝗹𝘆" 𝗽𝗿𝗼𝗰𝗲𝘀𝘀?
The "apply" process in Terraform involves comparing the desired state from your configuration to the current state, generating an execution plan, and then applying the changes.5. 𝗛𝗼𝘄 𝗰𝗮𝗻 𝘆𝗼𝘂 𝗺𝗮𝗻𝗮𝗴𝗲 𝘃𝗲𝗿𝘀𝗶𝗼𝗻𝗶𝗻𝗴 𝗼𝗳 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗰𝗼𝗻𝗳𝗶𝗴𝘂𝗿𝗮𝘁𝗶𝗼𝗻𝘀?
You can use version control systems like Git to track changes to your Terraform configurations. Additionally, Terraform Cloud and Enterprise offer versioning features.6. 𝗪𝗵𝗮𝘁 𝗶𝘀 𝘁𝗵𝗲 𝗱𝗶𝗳𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝗯𝗲𝘁𝘄𝗲𝗲𝗻 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗮𝗻𝗱 𝗖𝗹𝗼𝘂𝗱𝗙𝗼𝗿𝗺𝗮𝘁𝗶𝗼𝗻?
Terraform is a multi-cloud IaC tool that supports various cloud providers, including AWS. CloudFormation is AWS-specific and focuses on AWS resource provisioning.7. 𝗪𝗵𝗮𝘁 𝗶𝘀 𝗮 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗺𝗼𝗱𝘂𝗹𝗲?
A Terraform module is a reusable set of configurations that can be used to create multiple resources with a consistent configuration.8. 𝗛𝗼𝘄 𝗰𝗮𝗻 𝘆𝗼𝘂 𝗱𝗲𝘀𝘁𝗿𝗼𝘆 𝗶𝗻𝗳𝗿𝗮𝘀𝘁𝗿𝘂𝗰𝘁𝘂𝗿𝗲 𝗰𝗿𝗲𝗮𝘁𝗲𝗱 𝗯𝘆 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺?
You can use the terraform destroy command to remove all resources defined in your Terraform configuration.9. 𝗛𝗼𝘄 𝗱𝗼𝗲𝘀 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗺𝗮𝗻𝗮𝗴𝗲 𝘂𝗽𝗱𝗮𝘁𝗲𝘀 𝘁𝗼 𝗲𝘅𝗶𝘀𝘁𝗶𝗻𝗴 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲𝘀?
Terraform applies updates by modifying existing resources rather than recreating them. This helps preserve data and configurations.10. 𝗖𝗮𝗻 𝗧𝗲𝗿𝗿𝗮𝗳𝗼𝗿𝗺 𝗯𝗲 𝘂𝘀𝗲𝗱 𝗳𝗼𝗿 𝗺𝗮𝗻𝗮𝗴𝗶𝗻𝗴 𝘁𝗵𝗶𝗿𝗱-𝗽𝗮𝗿𝘁𝘆 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲𝘀?
Yes, Terraform has the capability to manage resources beyond AWS. It supports multiple providers, making it versatile for managing various cloud and on-premises resources.
Comments
Join the discussionNo comments yet. Be the first to comment.